Removing Data Discrepancies
Jay Vala
Removing Data Set Discrepancies
There were a lot of discrepancies in the dataset I created in the last step and I have detailed it in the most recent post. The most efficent way of removing those long sentences, and making them suitable for learning was making it of a fixed length.
I have used a technique called Sliding Window Protocol here is the brief example of how this is used here for breaking long sentences into smaller ones of fixed size.
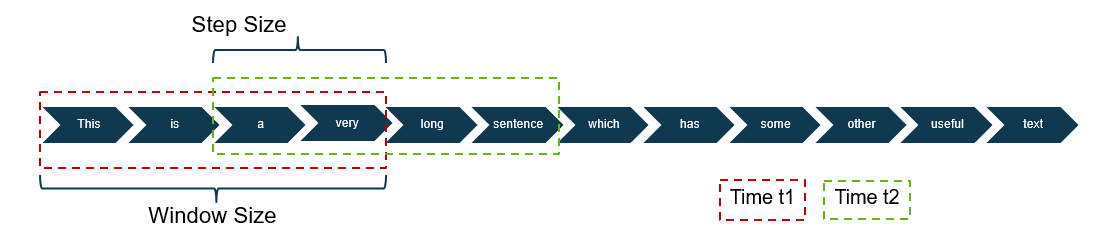
All the code will be the same from the last step but there will be a small change.
import os, sys
import pandas as pd
import numpy as np
# First lets create list of topics
label = []
for root, dirs, files in os.walk('/home/jay/GITHUB/Data_Thesis/Ready/'):
    label.append(dirs)
# Make a dictionary to hold the labels and corresponding category
labels = dict(list(enumerate(label[0])))
Now its time to write the sliding window function. Here the function slidingWindow takes three arguments, first one is the sequence that we desire to break, winSize is the desired window size(how long the sequence should be) and step is the number of words after the first word to the next sequence. The image above helps in clearing it out.
def slidingWindow(sequence,winSize,step):
    """Returns a generator that will iterate through
    the defined chunks of input sequence. Input sequence
    must be sliceable."""

    # Pre-compute number of chunks to emit
    numOfChunks = ((len(sequence)-winSize)/step)+1
    # Do the work
    for i in range(0,round(numOfChunks)*step,step):
        yield sequence[i:i+winSize]
NOTE: *Here I have rounded off the numOfChunks parameter. It is because the formula to calculate it would result into floating point numbers which can not be used in the range function. For example, if the length of sequence is 41 and winSize is 20 and step is 20 then the numOfChunks will be ((41-20)/20)+1 = 2.05 *
# Lets go through the files and take file name, dir name, and subdir name

sent = []  # List to store the sentence
label = [] # List to store the label(alpha)
label_num = []  # List to store numerical label

for root, dirs, files in os.walk('/home/jay/GITHUB/Data_Thesis/Ready/'):
    for file in files:
        if file.endswith('.txt'):
            topic = root.split(os.path.sep)[-2]
            with open(os.path.join(root, file)) as f:
                cont = f.readlines()  ## we prefere to get the sentences in the list form so that it is easy for us to label it


                # Store every sentence with its corresponding labels in a list
                # Get the label
                for key,value in labels.items():
                    if str(value) == str(topic):      # If the dir is equal to any value in the labels dict then
                        label_ = key


                for line in cont:
                    # Checks
                    if len(line.split()) <=5:   # If the sentence is less than 5 words, just ignore them
                        pass
                    elif len(line.split())>5 and len(line.split())<=20:  # If its betweenn 5 and 20 just add them to dataset
                        sent.append(line)
                        label.append(topic)
                        label_num.append(label_)
                    elif len(line.split()) > 20:
                        # break the lines into 20 words each
                        # for this I will use sliding window
                        slides = slidingWindow(line, 20, 20)
                        for slide in slides:
                            sent.append(slide)
                            label.append(topic)
                            label_num.append(label_)
Also there is a change in the way I am selecting the lines to be added in dataset. If the length of the line is smaller than or equal to 5 then I will ignore the lines, but I will not do it after the silding window, as there may be slides which have less than 5 words, I was removing it previously because it did not convey any meaning but I know for sure that after the silding window the lines will be from a bigger chunk of text which had importance so any small line from it will also be important.